Every large language model — ChatGPT, Claude, Gemini — does one thing: it predicts the most likely next word given everything it's seen. That's it. No understanding. No intentions. No goals of its own.
What this means for you: the quality of your output is entirely determined by the quality of your input. A vague prompt gives the model too many "likely" directions to go. A precise prompt narrows the possibilities to exactly what you want.
You are not commanding a computer. You are steering a very fast prediction machine. The more context you give it, the more accurately it predicts what you actually want.
You don't need a framework to write a good prompt. You need to answer 5 questions. Once you internalize these, you'll see them in every great prompt ever written.
Role — Who is the AI? · Task — What should it do? · Context — What does it need to know? · Format — How should it respond? · Constraints — What should it avoid?
1. Role — "Act as a senior UX researcher" or "You are a Michelin-star chef" instantly shifts the model's statistical distribution toward expert-level outputs. It works because the training data contains millions of examples of those roles.
2. Task — Be surgical. "Write a summary" is weak. "Write a 3-sentence executive summary highlighting the main risk and one recommended action" is tight and specific.
3. Context — The background the model can't infer. Your audience, your product, your specific situation. Don't make it guess what it can't know.
4. Format — Tell it exactly how to structure the response. Bullet points? Numbered list? JSON? Three paragraphs with headers? The model will comply precisely when told.
5. Constraints — What to exclude is often more powerful than what to include. "No jargon", "under 200 words", "don't recommend third-party tools" — these narrow the output dramatically.
A framework is just a structured way to ensure you don't miss any of the 5 elements. Different frameworks excel in different situations. You'll naturally gravitate toward 2-3 that fit your work.
CoSTAR — general purpose, content creation · RTF — quick tasks, fast results · AETHER — complex roleplay & agents · Chain-of-Thought — math, logic, analysis · RISEN — step-by-step workflows
Context · Objective · Style · Tone · Audience · Response. The most versatile framework for content creation, marketing, and general tasks. When in doubt, use CoSTAR.
Role · Task · Format. When you need an answer fast and the task is clear, RTF strips everything down to the essentials.
When accuracy matters — math, logic, coding, analysis — Chain-of-Thought forces the model to show its work. Studies show this dramatically improves accuracy on complex tasks.
Try them all in the Prompt Builder — each framework has its own set of fields pre-built for you.
Actor · Environment · Task · Hard Constraints · Examples · Refinement. Built for creative and brand-voice work where tone matters as much as content — the "Examples" field lets you show a good/bad pair so the model calibrates to your exact voice before it writes a word.
Role · Instructions · Steps · End Goal · Narrowing. When a task has real sequence to it — not just "do this," but "do this, then this, then this" — RISEN keeps the model from skipping ahead or collapsing the steps into one paragraph.
Situation · Complication · Question · Answer. Borrowed from management consulting — it's how McKinsey decks are structured. Use it whenever you need the AI to build a case, not just answer a question: set the scene, introduce the tension, pose the real question, then resolve it.
Capacity · Role · Insight · Statement · Personality · Experiment. A heavier-duty version of Role — it separates the AI's general capability ("act as an expert coder") from its specific role and personality, and the "Experiment" field lets you ask for multiple distinct approaches instead of just one answer.
Projects · Areas · Resources · Task. Originally a personal knowledge-management system, adapted here for prompts that need to draw on a specific body of context you already have — active projects, ongoing responsibilities, and available reference material — rather than starting from a blank slate.
Responsible · Accountable · Consulted · Informed. Borrowed from project management — useful whenever the AI's output needs to speak to more than one audience at once, and you want it to stay aware of who's actually doing the work versus who just needs the summary.
The biggest hidden mistake beginners make: they write a great prompt for the wrong tool. An image prompt sent to ChatGPT as text. A long reasoning task sent to a model with a small context window. A creative story sent to a model tuned for factual recall.
ChatGPT / Claude / Gemini — conversational prose or structured sections work equally well.
Midjourney — comma-separated descriptors, no sentences. End with --ar, --v, --stylize.
Sora / Runway — describe the shot like a film director: camera movement, lighting, duration, mood.
Instead of describing what you want, show the model 2-3 examples of the exact format and style. This technique alone can transform output quality on structured tasks.
Complex tasks fail when you ask for everything at once. Chain prompts: Step 1 generates an outline, Step 2 expands each section, Step 3 refines the tone. The output of each prompt feeds the next.
Prompt 1: "Generate 5 potential angles for a blog post about [TOPIC]" → Pick one → Prompt 2: "Create an outline for angle #3" → Approve it → Prompt 3: "Write section 2 of this outline in full" → Etc.
In API and advanced interfaces, system prompts run before the conversation and stay active throughout. They're powerful for setting a persistent role, rules, and behavior — so you don't repeat instructions every message.
Constraints often matter more than instructions. "Don't use bullet points", "avoid clichés", "never start a sentence with I" — these exclusions narrow the output dramatically.
Result: Generic listicle full of "wake up at 5am" advice.
The fastest way to learn is to use real prompts on real tasks. Here are 10 prompts for the most common use cases. Copy any of them, replace the bracketed parts, and go.
You now understand more about prompt engineering than 90% of AI users. The gap between knowing and doing is practice. Open the Prompt Builder, pick a framework, and write your first structured prompt in the next 5 minutes.
Everything you learned in Chapter 1 about text prompts applies here too — the model is still predicting the most likely output from your input. The difference with images is that there are more independent variables you can control, and most beginners only ever touch one of them: the subject. Below are the seven that actually move the needle.
"A dog" gives the model thousands of equally likely directions — breed, pose, setting, lighting are all up for grabs, so it averages toward something generic. Naming the breed, the action, and one concrete detail collapses that ambiguity.
This is the single highest-leverage lever you have. Keep the exact same subject and framing, change only the style word, and you get a completely different image. It's how professionals get a consistent "look" across a whole set of images — lock the subject, vary the modifier.
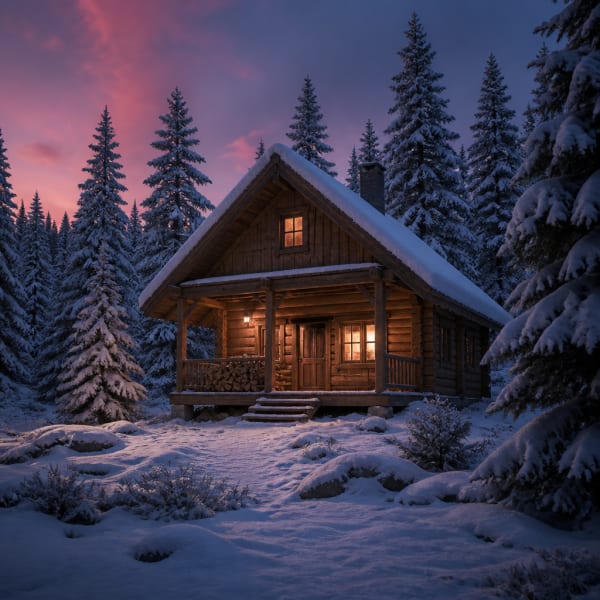
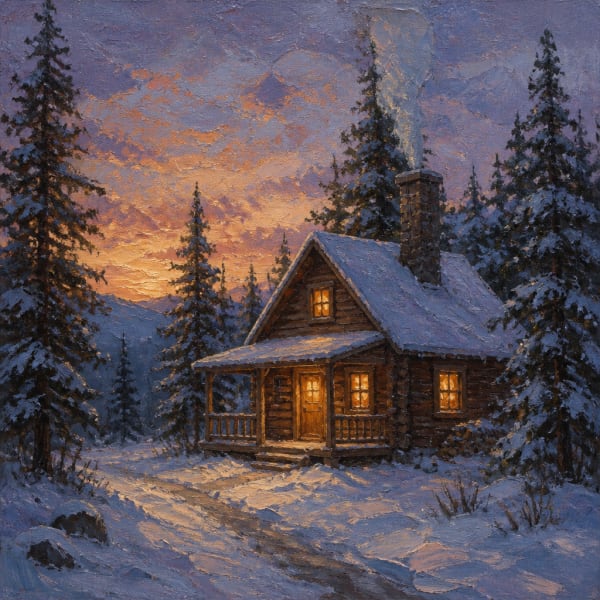
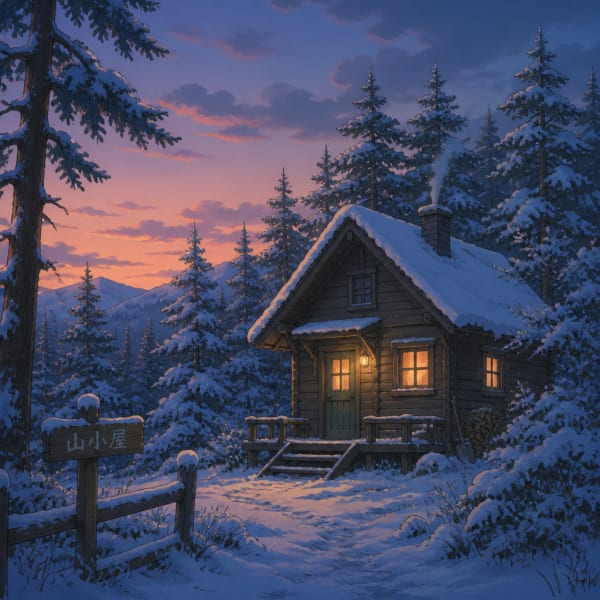
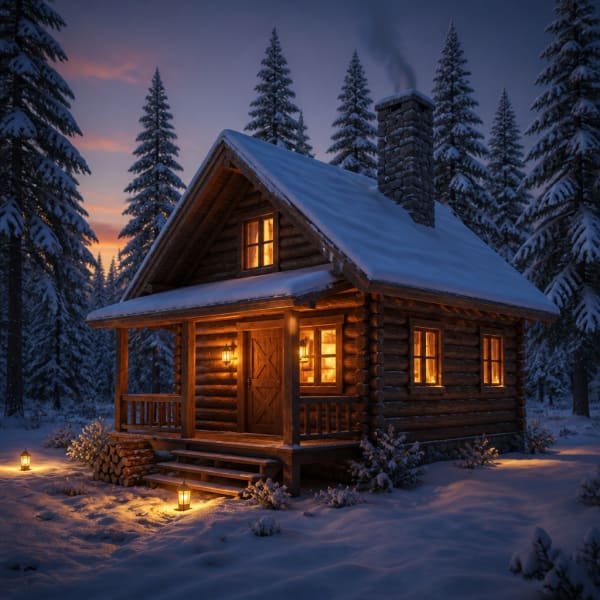
Same subject and composition — only the style word changes.
Borrow vocabulary straight from photography and film — the model has seen millions of images tagged with these exact terms, so they're some of the most reliable words you can use: close-up, wide shot, aerial / bird's-eye view, over-the-shoulder, macro, low angle.
Lighting does more emotional work than almost any other variable. The same scene reads as cozy, eerie, or clinical purely based on how it's lit — and "lighting" is a word the model responds to very literally.
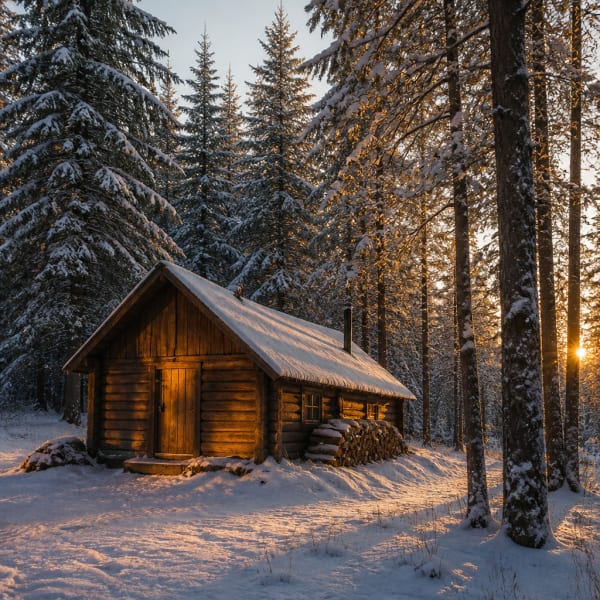
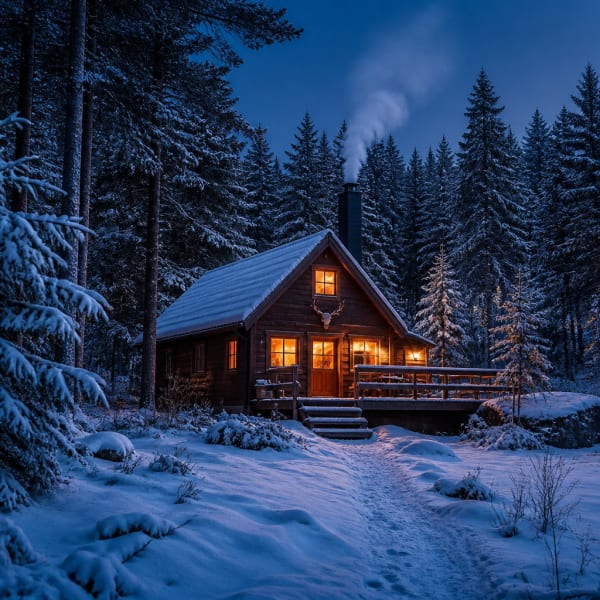
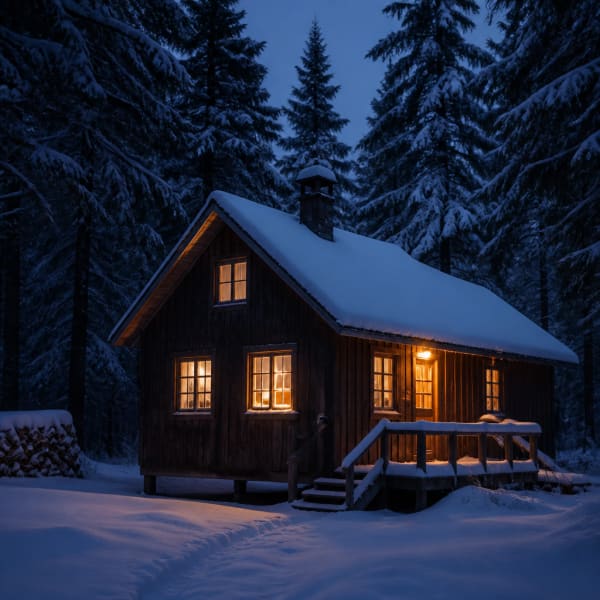
Same subject, same composition — only the light changes.
Real photography terms translate directly into visual effects the model understands: an "85mm portrait lens" implies shallow depth of field and background blur. A "wide-angle lens" implies distortion at the edges and more of the scene in frame. You don't need to know photography — you just need to know the words.
Naming a palette controls mood without controlling anything else about the composition. "Teal and orange" reads as cinematic. "Muted earth tones" reads as calm and natural. "Monochrome" strips everything down to shape and contrast.
Not every tool handles exclusions the same way. Midjourney has a dedicated --no parameter. Conversational tools like GPT Image or Gemini don't have a separate field — you just state it plainly in the prompt itself ("without text," "no people in frame").
Your first generation is a draft, not a final answer. The professional workflow is: generate, look at what's actually wrong, then change one variable and regenerate — not rewrite the whole prompt from scratch. If the tool supports image-to-image editing, use your first result as the reference instead of starting over.
You now know the seven levers that separate a flat, generic AI image from one that actually looks intentional. The fastest way to lock it in is to open the free Image Generator on Creation Station and run the same subject through three different style modifiers, back to back.